Deep dives into LLM architecture, post-training, and the bridge between research and production.
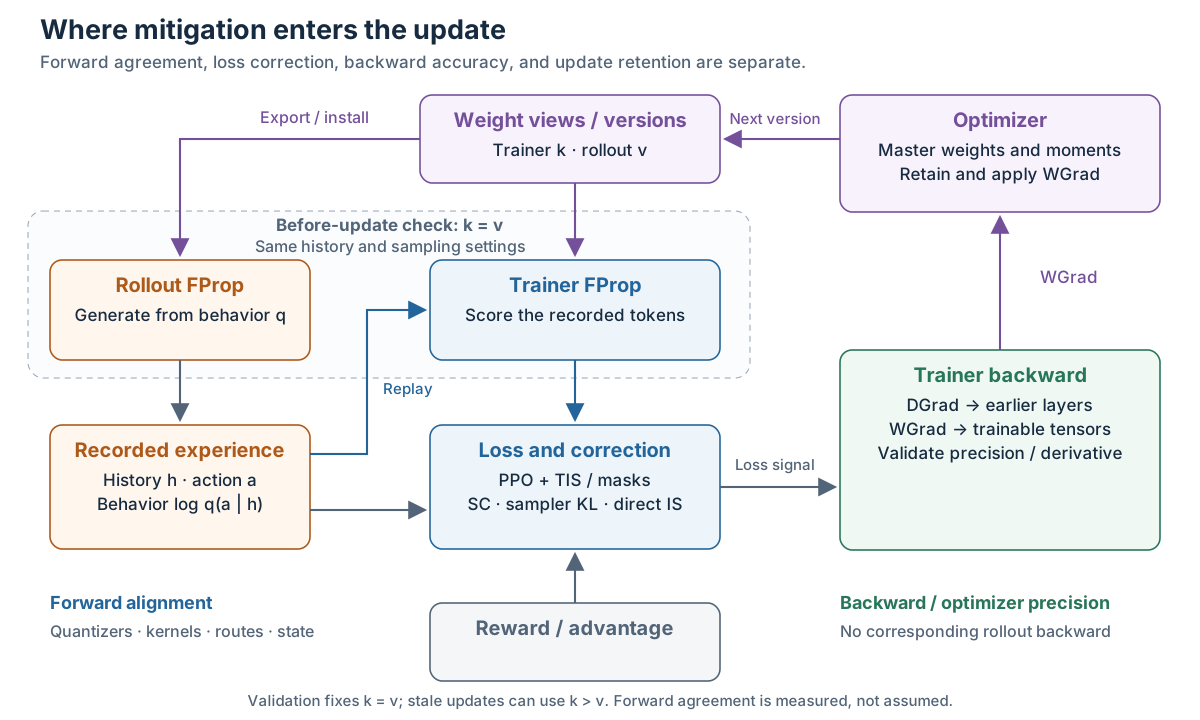
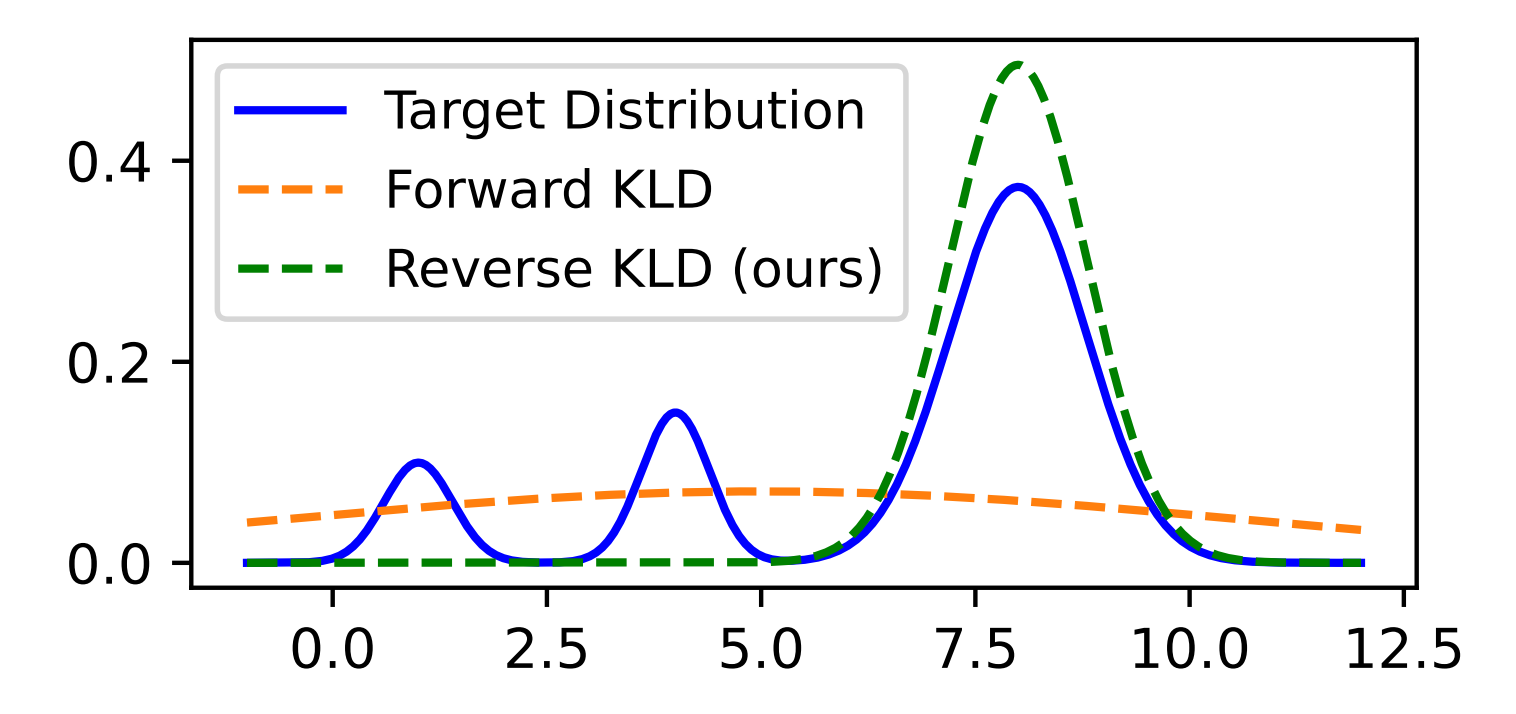
What PPO and rollout correction already handle, where forward alignment helps, and how score centering and REINFORCE Zero address the remaining disagreement.
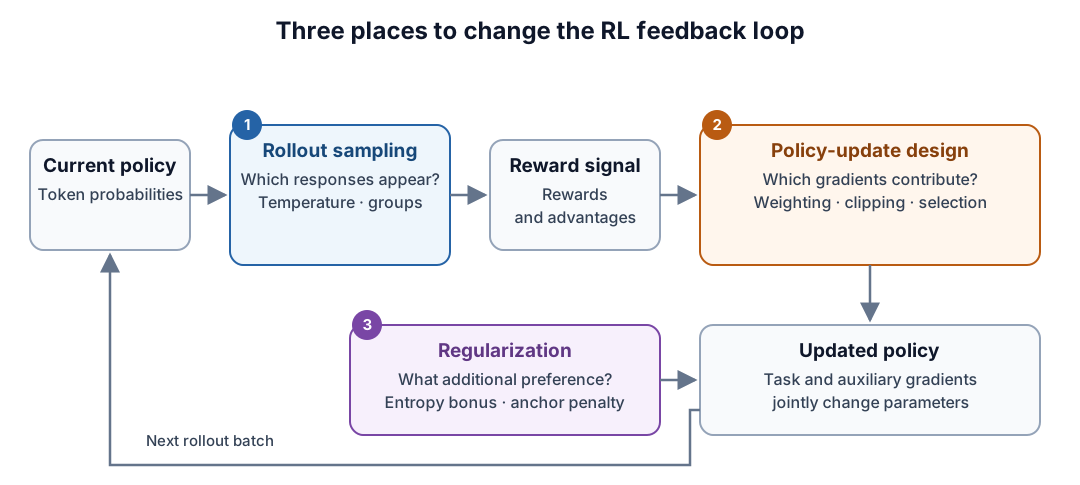
Why entropy collapse and uncontrolled growth can stall RL—and how update rules, regularization, and sampling shape effective learning.
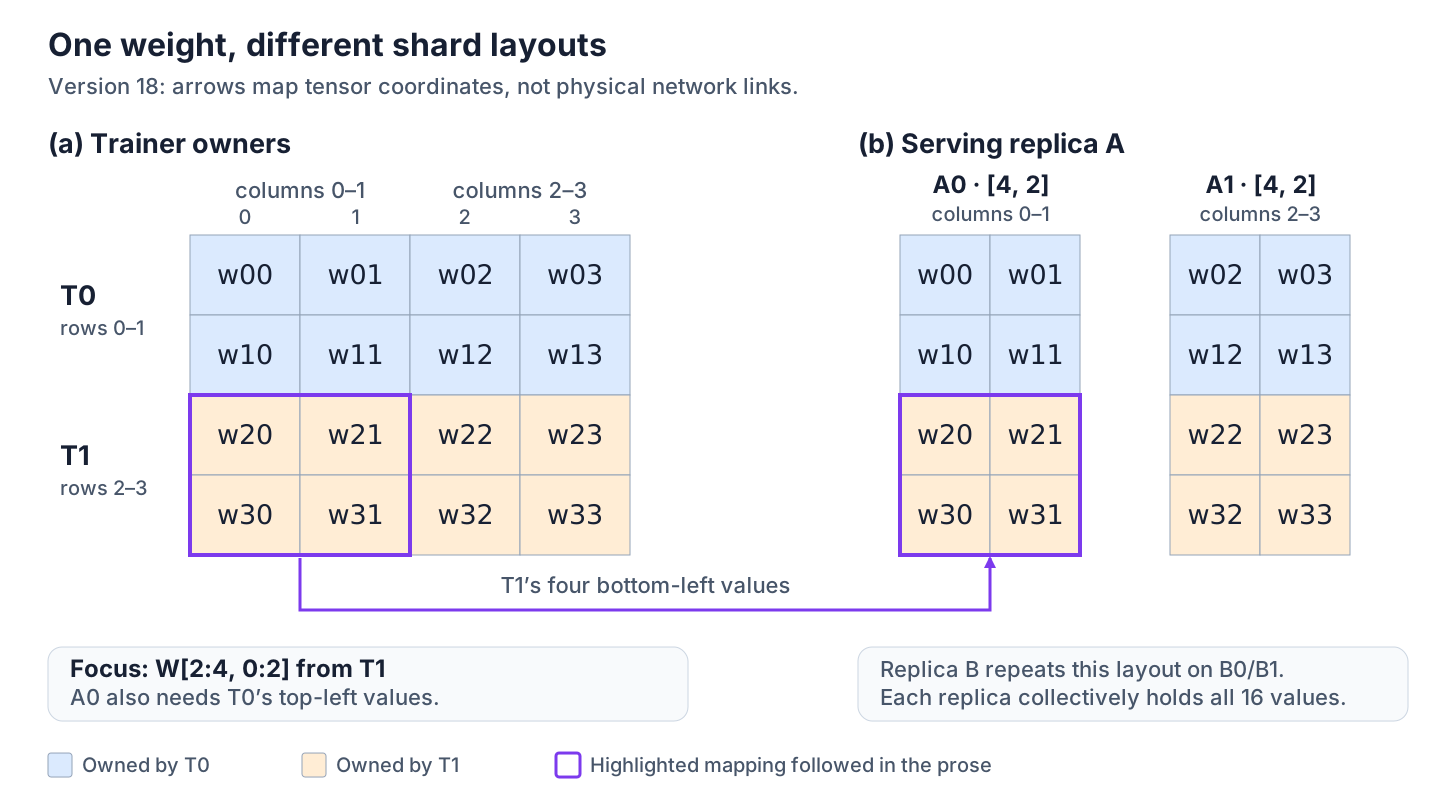
How distributed trainers deliver updated weights to rollout workers, reduce transfer and installation costs, and safely switch generation to a new policy.
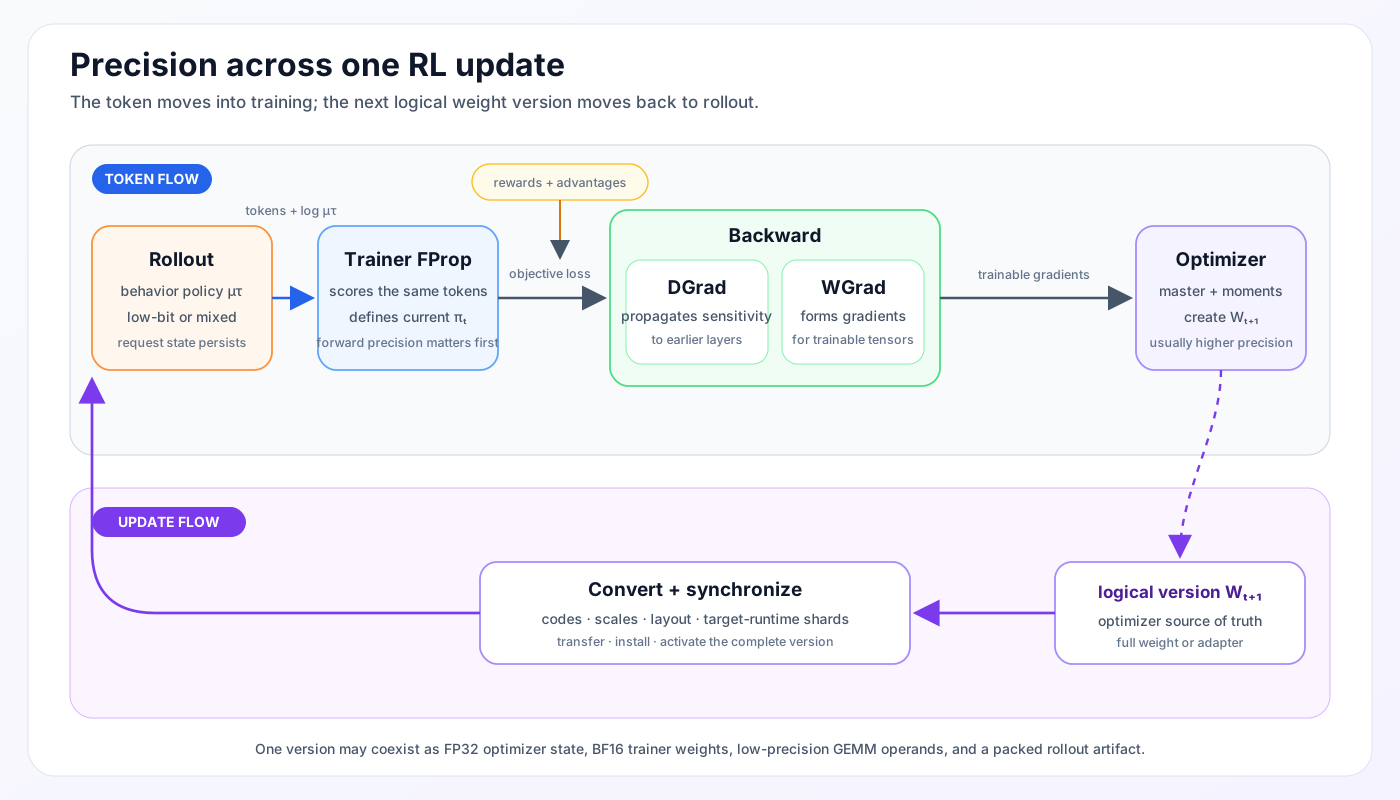
How precision choices across rollout, training, and synchronization shape the policy optimized by LLM reinforcement learning.
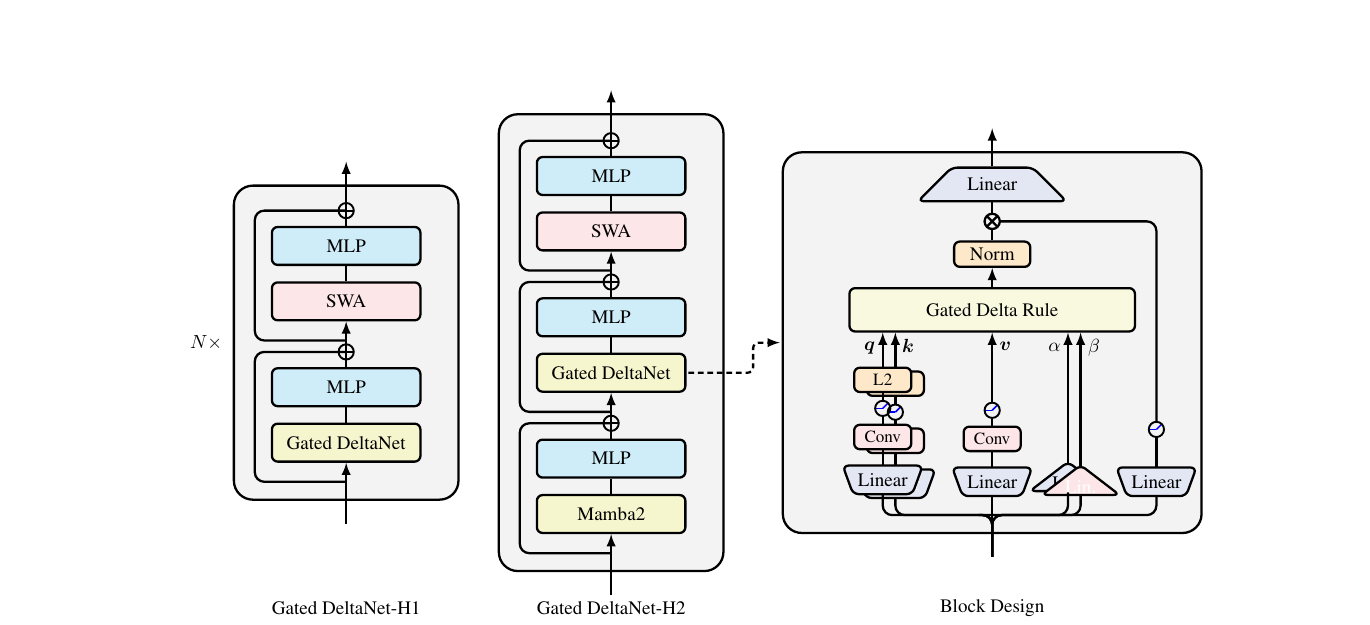
A technical note on the recurrent-state lineage from linear attention to KDA, K3’s hybrid stack, and DSA as a sparse-retrieval contrast.
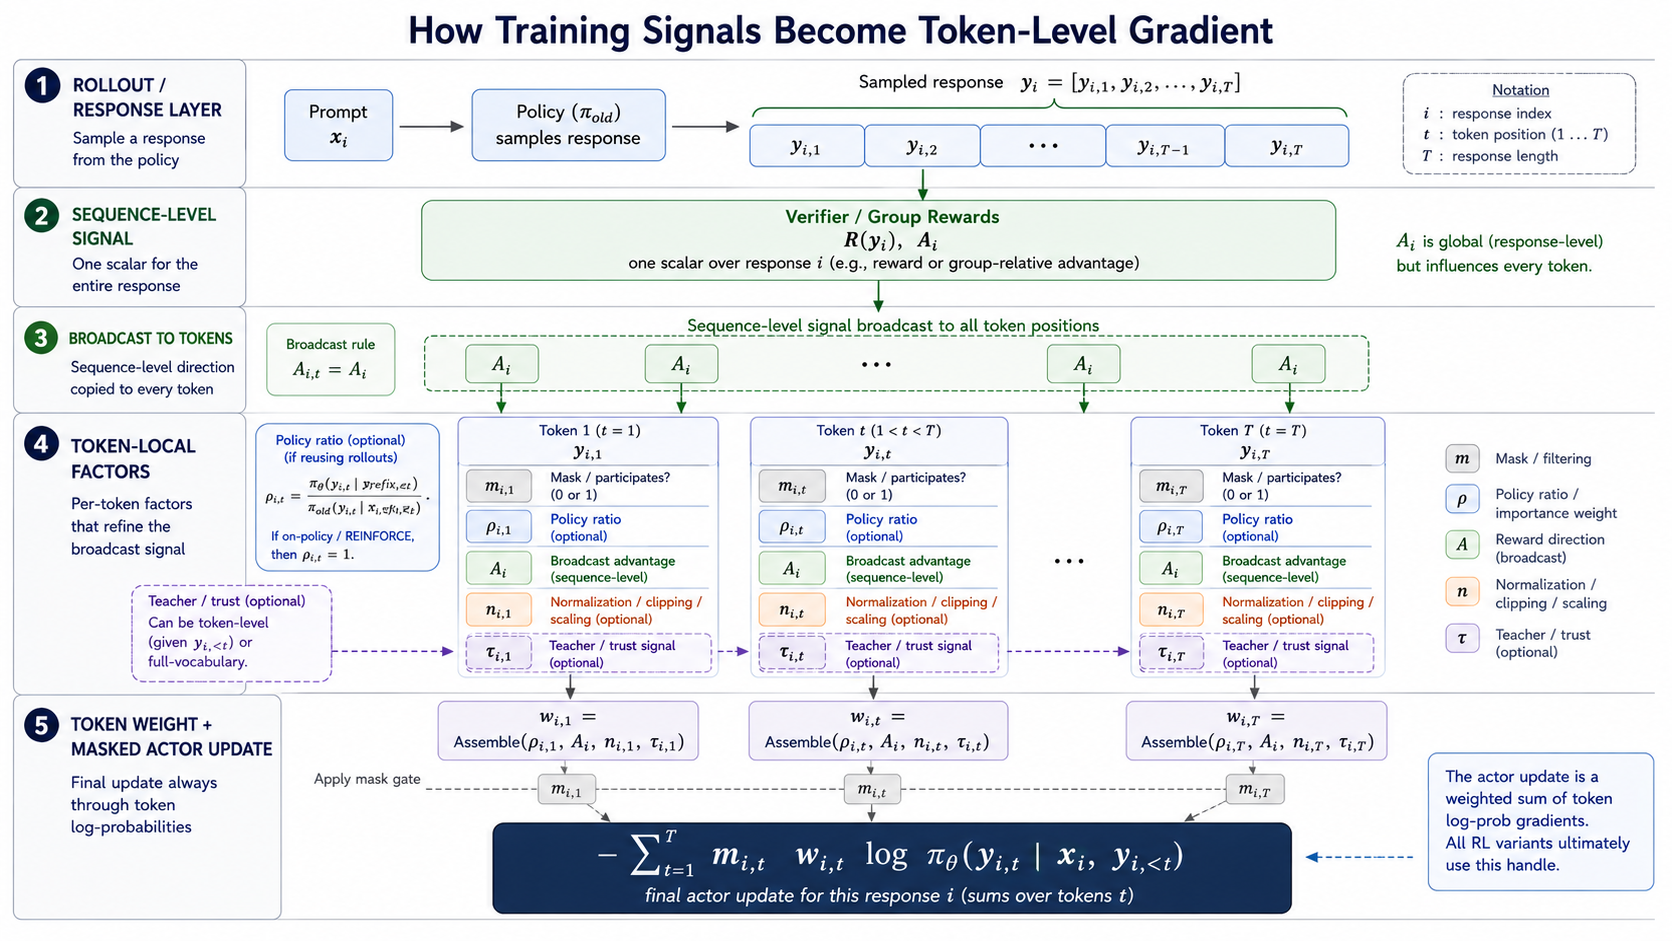
A token-weighting view of PPO, GRPO, DAPO, CISPO, SDPO, SRPO, RLSD, and the newer conditional-trust direction in on-policy distillation.
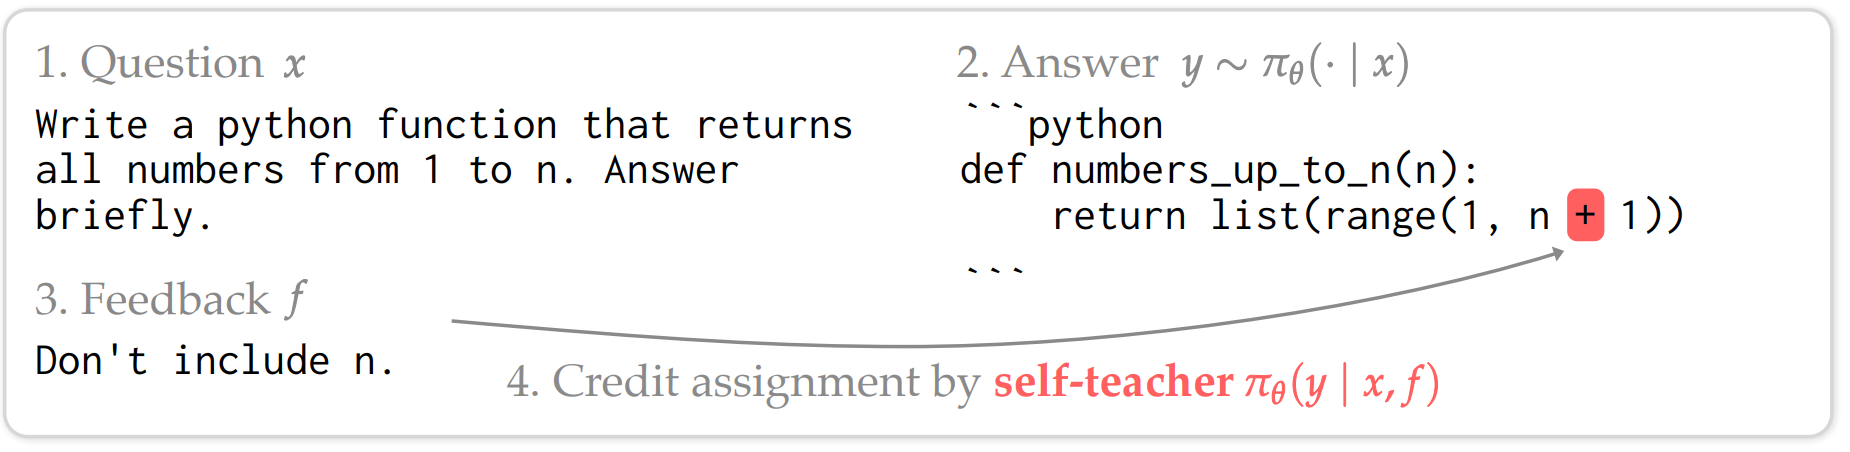
Why on-policy self-distillation is a natural complement to standard RL, and how SDPO, OPSD, and GLM-5 implement it.
Why standard SFT causes catastrophic forgetting, and how contextual on-policy self-distillation fixes it from first principles.
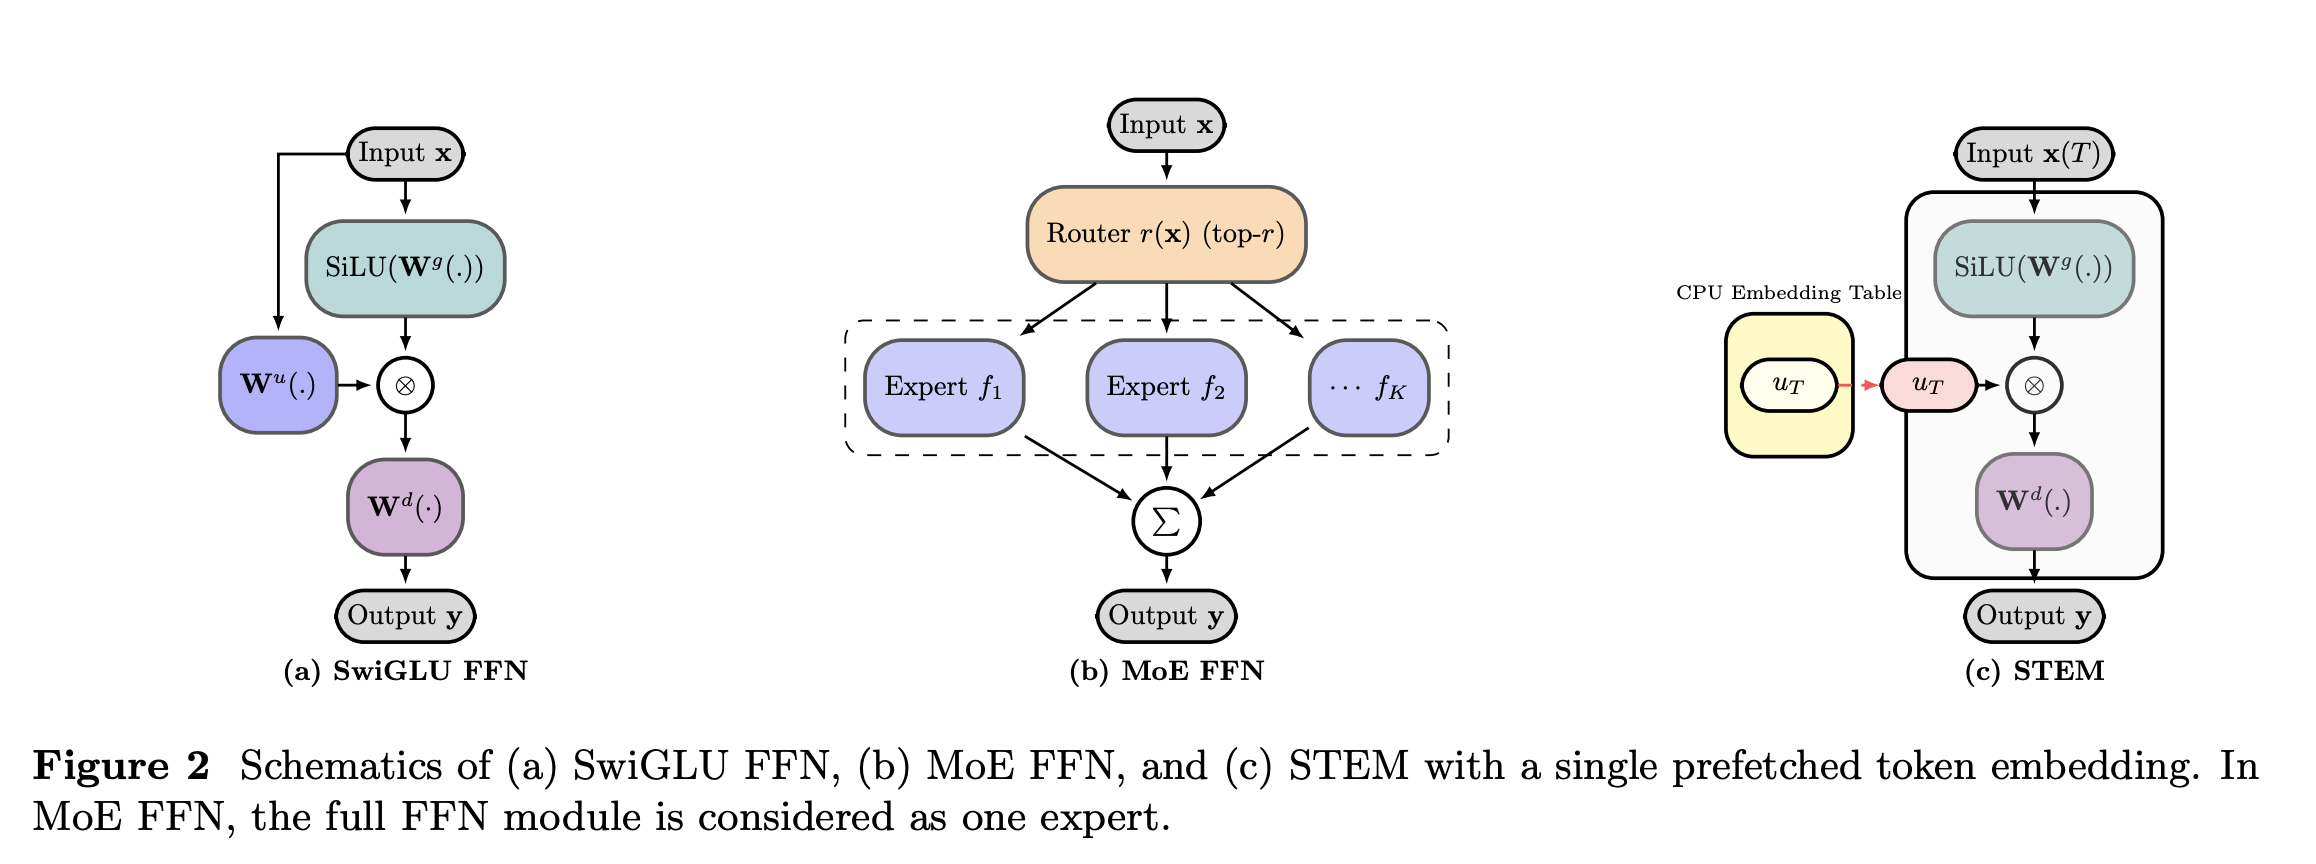
How PLE, STEM, Engram, and LongCat decouple knowledge storage from reasoning by moving static facts into embedding modules.